 quickdial
 Free for the first 100 on the list
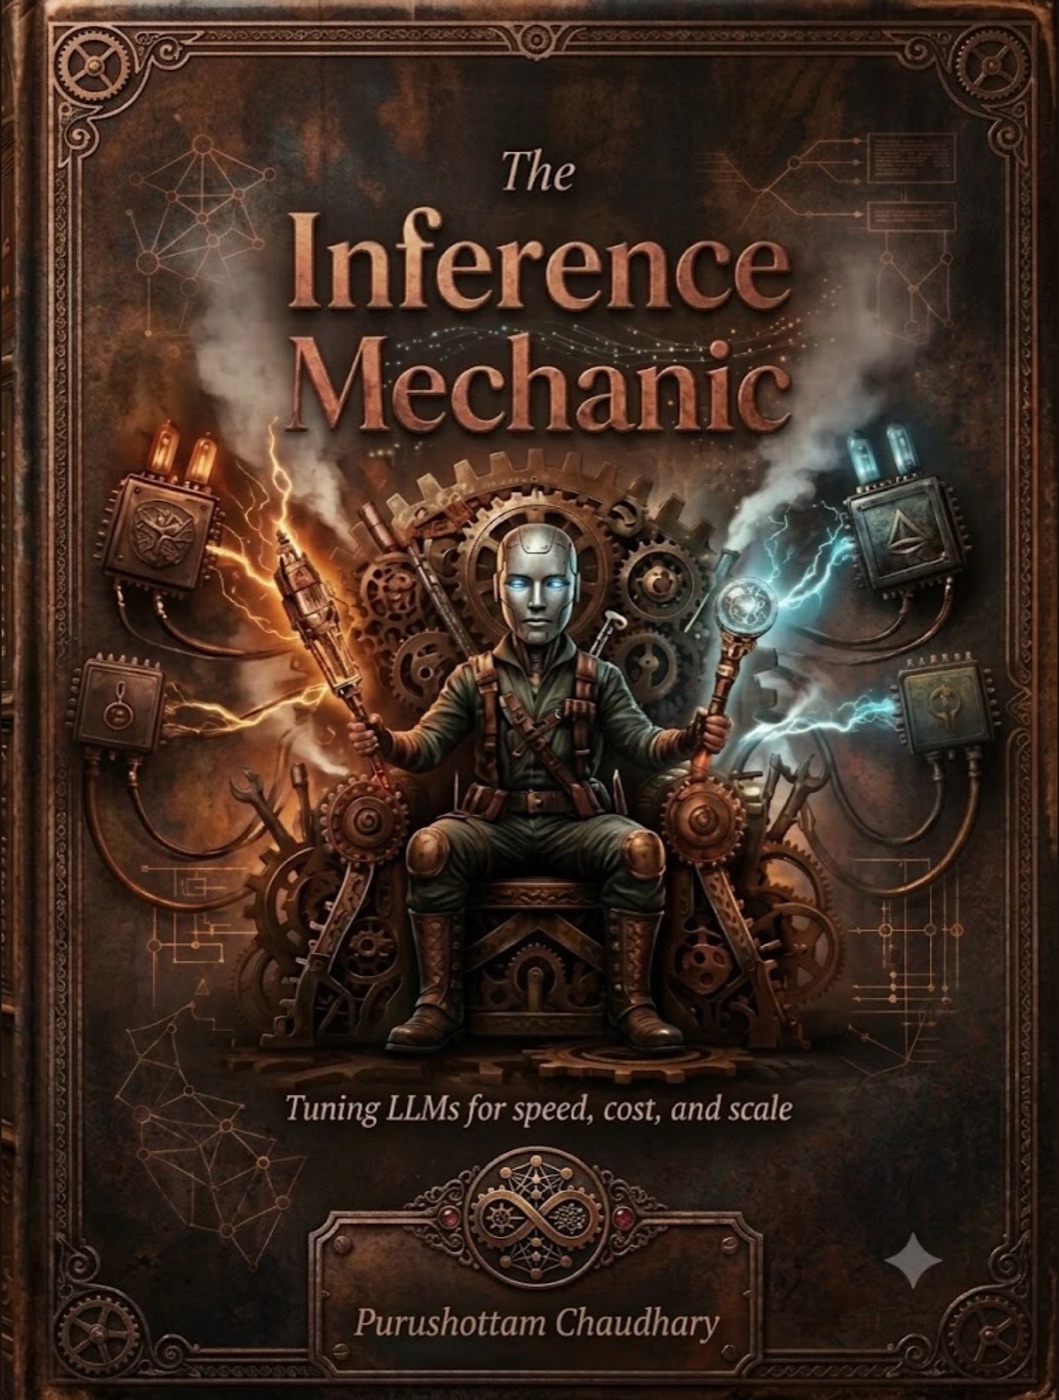
The Inference Mechanic.
Tuning LLMs for speed, cost, and scale.
A hands-on manual for the people who keep language models running: what the hardware allows, how a model is built and tuned, how one engine becomes a fleet, how to lock it down, and how far to the edge it can go. Every number in it is measured on real GPUs, not quoted.
By Purushottam Chaudhary — founder & CEO of QuickDial AI, the inference engineer behind a voice stack that runs under a cent a minute on commodity compute.
Under the hood, one system at a time.
The book follows the order a mechanic would: start at the metal, learn how the engine is made, tune it, then take it out on the road. Every technique ends with a three-gauge tune-up card — compute, memory, accuracy — so you know what it costs before you turn the screw.
- 01
Hardware and Its Limits
Memory bandwidth, compute, interconnect and where the decode wall really comes from. The numbers everything else has to respect.
- 02
Model Architectures
Transformers and their variants, mixtures of experts, small and decision models — and what each one costs at inference time.
- 03
How Models Are Made
Pretraining, fine-tuning, LoRA and distillation, read from the serving side: what a training decision does to your bill later.
- 04
The Tune-Up
Quantization, KV-cache strategy, speculative decoding, batching and compilation — the levers, and the gauge readings for each.
- 05
Beyond Text: Modalities
Speech, vision and multimodal pipelines, with their token budgets and latency paths, measured end to end.
- 06
From Engine to Fleet
Serving engines, packaging, Kubernetes and the fleet: turning one fast box into capacity you can price per minute.
- 07
Locks and Guardrails
Security for a serving stack — isolation, prompt injection, data handling and compliance — built into the engine rather than bolted on.
- 08
The Edge
Model formats, small language models, on-device and hybrid inference: how small a machine can still hold a conversation, and what comes next.
- +
On the Dyno
The rig, the catalogue of tests and the measured results behind every claim in the book. If it isn't on the dyno, it isn't in the book.
- Engineers shipping LLM features who pay the inference bill and want it to go down.
- Platform and infrastructure teams deciding what runs on which hardware, and how many boxes.
- Founders and technical leaders choosing between rented APIs, their own GPUs and the edge.
The first 100 readers get it free.
Leave your email and you will hear from us once, when the book ships. The first hundred people on the list receive the EPUB and PDF at no charge; everyone after that gets the launch price.
- One email when it ships — nothing else, no newsletter
- EPUB and PDF, read on anything
- Unsubscribe with one click, any time